Blog

  • Link collection, week of december 11th

    AI

    MemoryCache, augmenting local AI with browser data

    OpenSource macOS AP copilot using vision and voice

    Instructions on running local LLM on iOS

    Intel CEO against the CUDA moat

    FunSearch: Making new discoveries in mathematical sciences using Large Language Models, by Google DeepMind

    Advancements in machine learning for machine learning: Machine Learning compilers by Google Researc

    Programming

    Exploring the design space of “remote scene approximation“.

    Use the GPU, Luke! – a GPU programming tutorial for non-graphic-programmers

    Permacomputing Aesthetics: Potential and Limits of Constraints in Computational Art, Design and Culture

    Bitsy Museum Hack: bitsy is a really fun engine for creating bit-art powered web games, and this hack allows one to create a “museum”, a central hub from which several games or experiences can be accessed. It might be fun to integrate bitsy experiences in our high-dimensionality sites!

    Audio

    Instrument position in Immersive Audio: an empirical review of award-winning practices

    Web

    Launch of Brasiliana, a common place on the web for Brazilian museums (from September)

    Offpunk: a delightful command-line first browser, sort of a modern Lynx

    Media queries for HTML Video: building responsive video is very important for making interactive documentaries work on mobile devices

    Paperless: a self-hostable document archive platform, complete with OCR

  • New resources for the immersive web, week of December 11th 2023

    WebXR on iOS

    Motivated by coming across the embedded post on Mastodon, we looked into existing solutions for iOS.

    We found this one, which is very sleek, but a bit on the expensive side: https://launch.variant3d.com/

    Gaussian Splatting Explosion

    Meta: a collection of Gaussian Splatting stuff https://aras-p.info/blog/2023/12/08/Gaussian-explosion/

    SMERF: Streamable Memory Efficient Radiance Fields

    SMERF

    Relightable avatars

    https://80.lv/articles/new-relightable-animatable-realistic-avatars-from-meta/

    Gaussian Splat based SLAM

    https://neuralradiancefields.io/splatam-slam-with-speed-precision-and-gaussian-splats/

    Visual Editor for React Three Fiber

    Triplex is not actually a new project, but it is still in early access.

    ThreedTiles: a 3DTiles viewer for three.js

    Source code. Some really impressive demos, particularly the map and Berlin.

  • Some AI news, and EU regulation

    Some AI news, and EU regulation

    This ended up being a pretty weird post, juxtaposing technical releases and legal developments, we don’t know if we really managed to give it a coherent shape, but this is very much the complex space in which the future of digital humanities, and indeed the future of everything we do, is being shaped.

    There are a lot of powerful actors that are working to shape it in their favor, and they are not being secretive at all.

    AI stuff

    We’re working on a couple of audio-guide projects, and in one of them it would be really convenient to automate some of the work with an AI. Our current attempts are technically presentable, but honestly pretty boring. Think something like the Spot guide-dog from Boston Dynamics (what is up with their microphones?), but on your phone and without installation. We have built it, it works, we do not think it’s good enough, just like automated translations aren’t really good enough, compared to a good professional translator. Needless to say, we’re keeping our eyes peeled for the latest advancements. After all AI is guaranteed to disrupt us.

    Large Language Models are tools, and it’s up to us how we use them, from Giant Robots Smashing Into Other Giant Robots.

    The EU Council and Parliament have reached an agreement on the new AI ACT. Before the agreement OpenFuture had written about copyright opt-outs, about friction and governance and about self-regulation.

    Local AI

    Sticking to AI, it seems that Google is catching up to ChatGPT, confirming our “there is no moat” position. However, just like Threads and Horizon Worlds, it is not coming to the EU yet, which we consider a worrying trend.

    We suspect it’s going to end up just like cloud computing: there is a lot of money to be made, but it’s going to be so capital-intensive that only a few big players will dominate the market, developing useful products that are hamstrung by the imperative to build in vendor lock-in. Luckily there are some really interesting developments on the local deployment side, and we think that the transparency and user control of locally run Open Source software are going to be extremely important.

    Mozilla published a guide for new AI developers last month, but last week they also published Llamafile, which combines llama.cpp and the brilliant Cosmopolitan library to distribute Large Language Models as single files.

    In a similar vein Noiselith allows us to run Stable Diffusion XL and generate images on local hardware, with a user-friendly setup.

    Voicemod allows to change your voice in real time, both to existing voices and to newly generated ones. We do not agree with The Verge’s disregard for the legal aspects of voice cloning, rights limiting the reproduction of one’s likeness are well established, copyright is not the issue.

    Apple released a Machine Learning framework for Apple Silicon, and they literally just pushed it on GitHub without announcing it. Of course nothing that Apple does passes unnoticed, the tech press was instantly on it.

    The ex-Apple employees behind Shortcuts have a new desktop AI startup.

    Meta, IBM, Intel, and around 50 other organizations launched an alliance for Open Source AI.

    Mistral AI, the French company that releases Apache-licensed models (their benchmark scores are pretty amazing), has received a $2B evaluation.

    AI Trust

    Meta has a new AI trust and safety initiative, but at a glance it seems like it’s mostly focused on spotting content that does not align with what the owners want, which is obviously super important.

    The most important article on AI trust you’ll read this week: AI and Trust by Bruce Schneider.

    Stuff at the intersection between law and culture

    Getting back to EU legislation, Felix Reda (of Pirate Party fame) and Justus Dreyling wrote about the need for a Digital Knowledge Act, highlighting the need to achieve something that is very much in line with our mission: allowing every research question to be done online. It should never happen that a document or a resource is held in a public archive or is made with public money (we’re thinking of scientific papers) and not be made available, online and for free.

    Cory Doctorow wrote on the evils of DRM, and that is always important to keep in mind when building digital archives and collections.

    The EU Data ACT is also moving forwards, with some good stuff (harmonization and foreign transfers, in particular) and some really concerning bits. Offering legal protection to trade secrets favors some specific players, but it is opposed to the hard bargain that makes patents exist. The current discourse seems to have lost sight of the fact that “Intellectual Property” is not property at all, in the abstract all knowledge should belong to every human being, we have setup a legal system that exchanges a temporal monopoly for technical information (in the case of patents) or as an incentive for the creation of more cultural works (in the case of copyright). Trade secrets should not be legally protected, if you want protection you should use patents. The current Data Act agreement also restricts reverse engineering, which is terribly harmful for innovation and competition.

    Work has also been progressing on the EU Cyber Resilience Act. It seemed to go in a weird direction for what concerns the intersection between security and Open Source, but they seem to have already fixed the most glaring issues. This is a good chance to recommend following Bert Hubert, he always has insightful articles and up to date news. For example that’s how we learned about this case in which Sony attempted to strong arm a DNS provider.
  • New resources for the immersive web, week of December 4th 2023

    We’re starting a new series, periodically highlighting new tools and advancements that help to build immersive experiences on the open web. Look for more of these posts in the tools category. These can be new products, significant updates, or simply new discoveries.

    A-Watch

    A small library for building watch-like user interfaces in a-frame, supporting hand tracking. There is even a demo, and here is the announcement tweet with a brief video.

    Gaussian Splat support for Three.js

    Three.js is the basis for a lot of immersive web experiences, including a-frame. drei-vanilla is a collection of threejs modules and helpers, and they just released a splat module, which allows for the inclusion of multiple splats in a scene with the <Splat src={url} /> syntax.

    3D comic dioramas with Needle Engine

    This one is not a new tool, but an interesting use of an interesting tool.

    Las Vegas Sphere with custom shaders

    The Sphere in Las Vegas is a super cool engineering project. Weirdly enough the public reaction seems to focus more on the external part, which is being used for ads, and meta-ads like this one:

    This is multiple levels of meta: it’s an ad showing that they’re using the sphere for an ad, it’s an immersive ad for an immersive product, and it’s literally by Meta

    Developer Alexandre Devaux (who regularly posts super interesting webXR projects, check out this splat experiment of his) created a threejs page in which one can apply an arbitrary shader to the sphere. There are 5 examples, and you can also write your own, or copy-paste from the Hacker News thread, the smiley face is an highlight.

    JSAR DOM

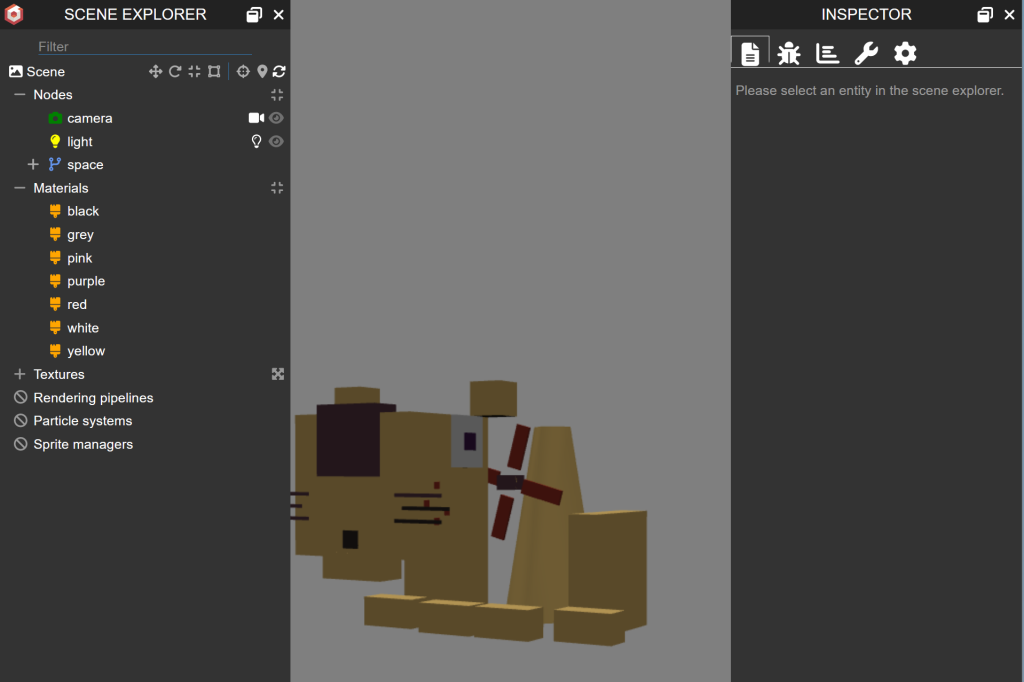
    This one is a little exoteric. There is a company called Rokid, they make AR glasses and some pretty interesting software to go along, especially related to human-computer interaction. They seem to have several laboratories, one of which is called M-CreativeLab, and they run a project called JSAR, which is somehow related to the YodaOS used on the Rokid AR glasses. They have developed XSML, yet another 3D HTML-like language, SCSS, a spatial version of CSS, and a TypeScript runtime. Combined together these allow for the creation of web-based 3D scenes that can be embedded in a website or inside a native application. There is support for Babylon.js and Unity, and a Visual Studio Code extension.

    There are a couple of demo scenes in their GitHub repository, which can be tested in a XSML runtime. For example we can go here: https://github.com/M-CreativeLab/jsar-gallery-flatten-lion, copy the CDN link https://cdn.jsdelivr.net/gh/M-CreativeLab/jsar-gallery-flatten-lion@main/lib/lion.xsml and paste it into the runtime hosted here: https://m-creativelab.github.io/jsar-dom/

    We’ll get the scene in the Babylon.js inspector. The cool thing is that the XSML file is very easy to understand, for anyone who knows HTML.

    As a personal aside, my one point of criticism is how much of the documentation, and even how much of the code, is written in Chinese. I strongly believe that computers should be used in English, and that having a lingua franca for technical work is extremely important, but I suspect this is now considered part of my 90s techno-optimism. Coming from a native English speaker it would also probably sound like some sort of xenophobia, luckily that’s not the case.

    Simulate 3D plants in the browser

    Extremely interesting plant simulations by undergrad (serious kudos!) Max Richter. The graph editor is so nice to play with!

  • Unlocking value from digital heritage collections: international perspectives

    Back in October we missed this rather interesting conference on digitalization and reuse, hosted by the University of Turin and shared on YouTube by Wikimedia Italia.

  • The Italian Court of Audit recommends Open Access for cultural works

    As reported by Wikimedia Italia, the Italian Court of Audit (Corte dei Conti) recently released a lengthy (220 pages!) report (source) on the activities of the Italian Ministry for Culture, touching on the PND (Piano Nazionale di Digitalizzazione) and on specific pricing guidelines released in April (D. M. 161, 11 aprile 2023).

    Ideologically we are pretty much aligned with Wikimedia’s position, but as a regular company that has to make money to survive, we can see the point of charging fees, if they were to generate significant revenue for museums and for those carrying out digitization and preservation efforts. We suspect that the monetization approach imagined by D. M. 161, 11 aprile 2023 is never going to generate significant revenue.

    Instead, as the Court of Audit report rightly points out, on page 155, the problems with the current approach are that it neglects dissemination, and prevents the kind of free reuse that generates value, which is not the same thing as revenue. Simply put, many potential users are dissuaded by the very possibility of having to negotiate a license.

  • Access and Recall

    Anyone who creates digital experiences should read Cory Doctorow, particularly his blog, Pluralistic.

    Recently he wrote this essay which touches on immersive digitization efforts for museums, which obviously hits close to home for us. In particular, this linked presentation by Aaron Cope explains the important concepts after which we’re titling this post. Check out his blog more generally if you’re interested in digital humanities and museums.

    We want to provide access to works and places, bridging over limits of time, space and economic resources. This has both a technical aspect, related to the digitalization of 3D objects, of their shapes, visual and acoustic properties, and a legal aspect, related to the various ways in which powerful entities attempt to extract rents from what should be a public good.

    The beauty of the web is that it allows regular people to bypass the agenda-setting role of media, we can independently publish, but also independently choose what to focus on, at a time of our choosing. We don’t have to follow the zeitgeist, we can focus on any point of the past, we can recall what we want.

    The kind of server technology we choose, with the exception of this blog, is oriented towards permanence. While cloud providers and server-based dynamic technologies have significant recurring costs, our static client-based solutions can just keep going for decades. We don’t participate in the “metaverse”, we put artworks and experiences on the open web, for all to partake.

    Quoting Aaron Cope once again:

    The web gave us the ability to return to a thing outside the shared (or master) narrative at a time of one’s own choosing. Of shifting time in the service of one’s own interest or in the service of simply coming to an understanding of one’s own interests.
    It lowered the barrier to speak to the future and to listen to the past. Not because we know why or can quantify its return in advance but because we believe what is most important is simply the ability to do so.

    Our visitors don’t have to be online at a specific time, they don’t have to use a specific device.

    Offline museums are obviously massively important, they are unparalleled at preservation tasks, but the access they provide is limited in several ways. The most obvious ones are geography, time and money, but we cannot forget about sensory accessibility, and the sheer lack of space. Most items in any museum collection just sit in an archive, and they will never be shown.

    It is also very hard to show items in their context, and particularly in their working contexts. We have worked on the digitalization of a dynamic sculpture, that would be rapidly destroyed if visitors were allowed to physically manipulate it. Similarly it is possible to share digital reproductions of working digital artefacts. For example Dominic Pajak created this BBC Micro that works both on regular devices and in XR. It is a full reproduction of both the hardware and software of a seminal 1980s computer, that none of us have ever had an opportunity to interact with in real life. The only place to experience this kind of computing history physically is the Computer History Museum in Cambridge, UK, but there are massive limitations.

    That brings to the legal aspects. Italian legislation places heavy restrictions on the reproduction of cultural heritage artworks, that go way beyond the already draconian copyright regime we live in. For software conservation the situation is even worse, the source code is generally not available, without maintenance everything stops working relatively quickly, and often the only viable conservation strategy is a combination of emulation and blatant piracy.

    Our promise is to deliver accessible web experiences that take advantage of immersive technologies, but are not beholden to them, and to do so at a price point that is competitive with regular websites, with no lock-in.

  • ActivityPub enabled

    Thanks to the official WordPress ActivityPub plugin this blog can now be followed on Mastodon, or any other Fediverse network.

    These days we’re working quite a bit with RSS feeds and the concepts of federation and syndication. We have a couple of super basic RSS-feed generators based on web scraping, one is for the news posted by Italian municipalities, the other for Threads.net profiles. Combining something like that with one of the many RSS to ActivityPub bridges it could be possible to follow local news and Threads users right from Mastodon.

    Getting closer to our core business, what would a Fediverse of 3D spaces look like? What about a Fediverse of spatial audio?

  • A 3D reconstruction comparison

    A 3D reconstruction comparison

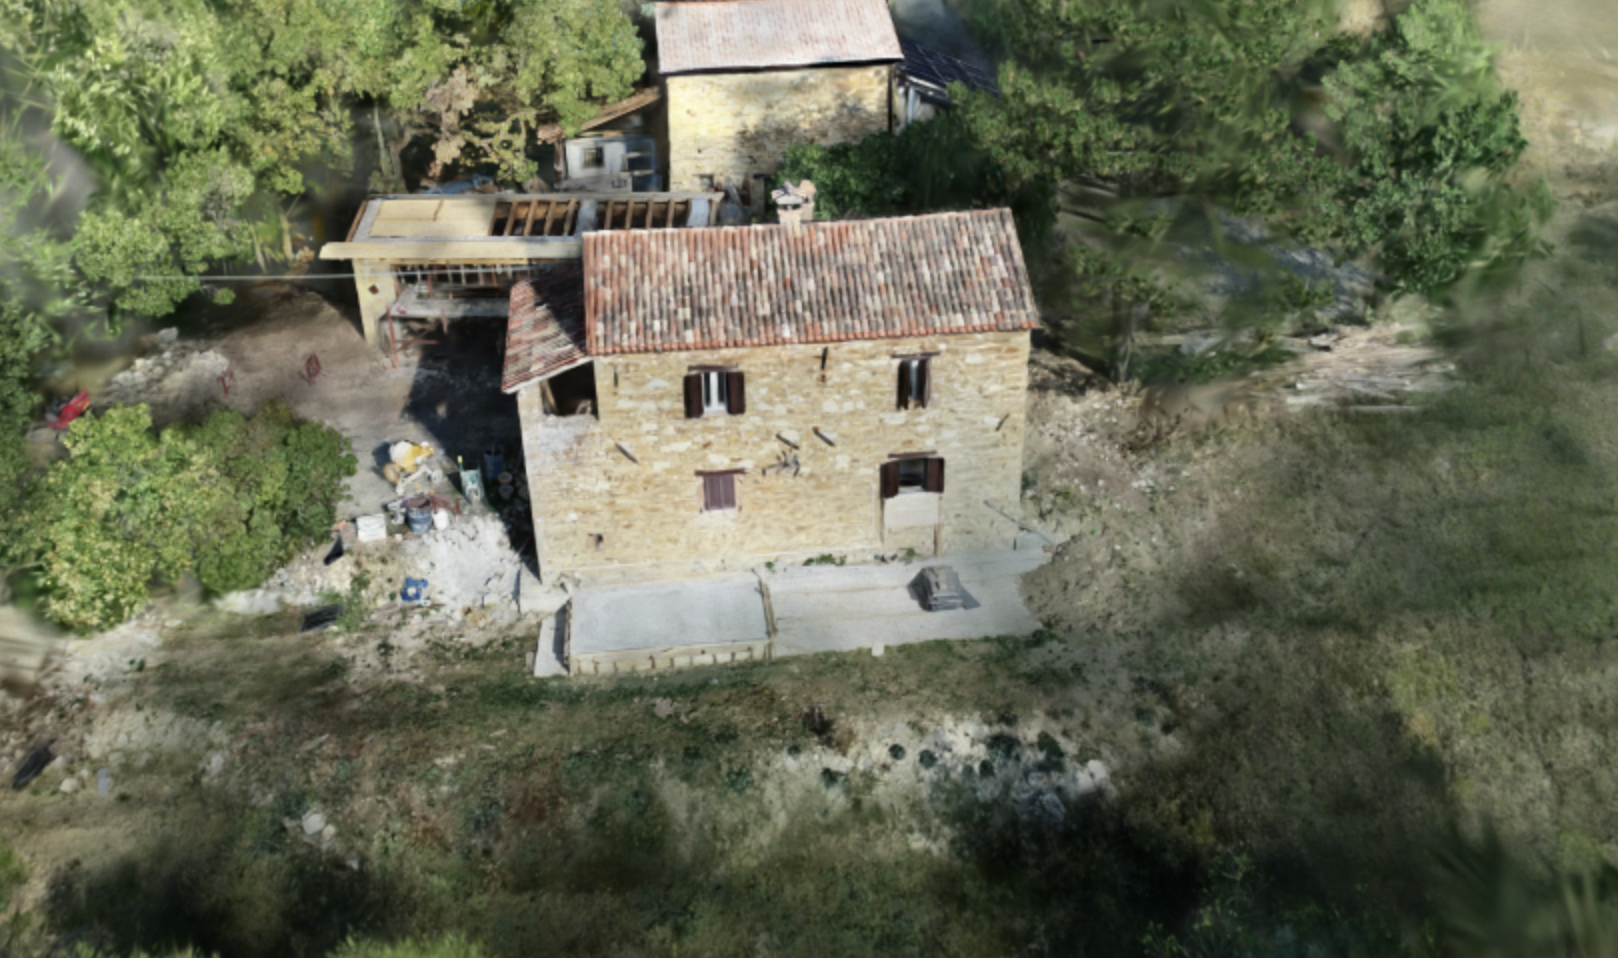
    In the past few weeks a new reconstruction technique has been taking the community by storm, called Gaussian Splatting. It is sort of an evolution on NeRFs, and mathematically it’s not dissimilar from the kind of reconstructions we do for spatial audio.

    Luckily a couple of companies have already implemented Gaussian Splatting pipelines, and here we are comparing two of them with photogrammetry.

    Here is Luma AI:

    Polycam

    And finally a photogrammetry computed with PhotoCatch (which uses Apple’s ObjectCapture API, like Polycam’s photogrammetry), converted to GLB in Blender to stay under Sketchfab’s size limit. In practice the only modification is that the textures are in JPEG instead of PNG.

    The difference is particularly evident in the textures on the building, and it’s just staggering on the vegetation.

    Also there is a small caveat: Luma was given a video, Polycam was given 200 photos, PotoCatch was given around 250 photos. This reflects differences in the platforms themselves.

    Update 2023-10-12: There is already an A-Frame component for self-hosting Gaussian Splats, we’re going to try it real soon.

  • MIMO Technique applied to the Greek Theatre of Tyndaris

    MIMO Technique applied to the Greek Theatre of Tyndaris

    We just published our first paper as a proper company! Check out the full text here.

    We created a reconstruction of the current state of a Greek-Roman theater in Sicily using drone-based photogrammetry, we helped with the acoustical measurements using the MIMO technique, and we created a Unity application that allows users to move around the theater, experiencing both the acoustics and the visuals in different stages of history.

    We also created a webXR version, which only shows the current state of the theater, and which doesn’t perform a proper reconstruction of the reverberation yet, but which you can try right now, on any device!